How Does Google Search Work? The One-Second Journey of a Search
When you tap Search, Google does not look at the internet; it searches its own copy. The first episode of Behind the Screen: crawling, indexing, ranking and three ways to check whether your site is on Google.
You type a question into your phone, tap Search, and the answer is on the screen in under a second. Most of us imagine that in that second Google races across the whole internet to find what we asked for. In fact, Google does not look at the internet at all at that moment. It pulls the answer from its own copy, one it has been reading and saving for months.
This article is the written version of the first episode of Behind the Screen (Ekranın Arkası), a series on our YouTube channel. Each episode looks at the real machinery behind a technology we use every day. You can watch the video or just read on. The illustrations in this article are the scenes from the video. The video itself is in Turkish.
In short:
- When you search, Google does not search the internet. It searches its own index, a copy of the pages on the web.
- A page has to pass three stages before it can appear in search: crawling, indexing and serving results.
- A page that is not in the index cannot be found on Google, even if it is live. The most common causes are a forgotten noindex line or a page that no other page links to.
- You can check whether your site is indexed yourself with a site: search and with Search Console.
Google does not search the internet when you search
There are hundreds of billions of pages on the web. If Google opened them one by one for every search, the answer would never arrive in a second. So Google does the work in advance: it reads pages, analyses them and stores them in its own archive. That archive is called the index.
Think of the index at the back of a book. To find the word "photosynthesis" you do not read the book from cover to cover; you check the index at the back: photosynthesis, page 112. That is exactly what Google does. The only difference is that the book is the internet itself.
According to Google's own explanation, this index holds hundreds of billions of web pages and is well over 100,000,000 gigabytes in size. That sentence has an important consequence for site owners: a page that is not in Google's copy does not exist for Google. The page may be live, it may look great, it may have been paid for. If it is not in the index, there is no way to find it in Google Search.
1996: a LEGO box, a googol and a garage
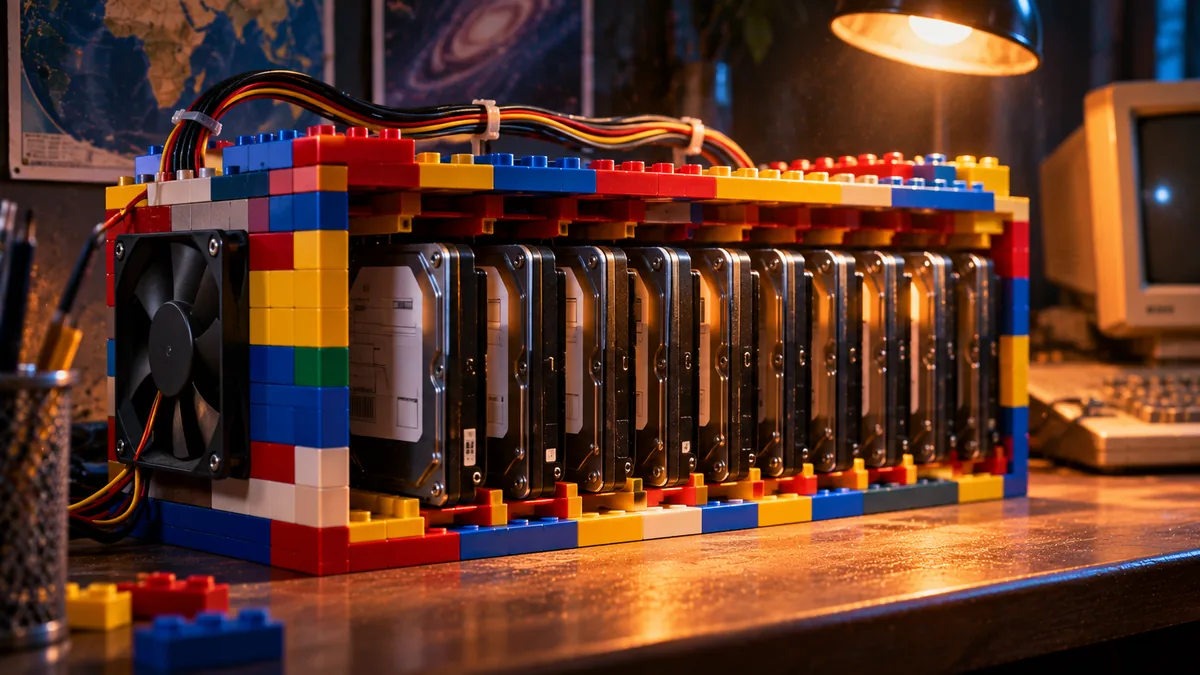
The story begins in 1996 at Stanford University in California. Two PhD students, Larry Page and Sergey Brin, are working on a research project with a slightly odd name: BackRub. Instead of a ready-made case, they line up their hard drives in a box built from LEGO bricks. The first version of the search engine that billions of people use today was running inside colourful toy bricks.
When the project needs a new name, they have the word googol in mind: the name of the number you get by writing 1 followed by a hundred zeros. According to the account kept in Stanford's archive, while checking whether the domain name was free, the word was mistyped as "google". They liked the spelling and it stuck. The domain google.com was registered on 15 September 1997. In 1998 the company was founded, and its first office was the garage of a rented house in Menlo Park.
The problem those two students solved is still at the heart of Google today. To understand it, let us look at the three jobs Google does every day.
Google's three stages: crawling, indexing, serving results
Google Search Central's documentation splits search into three stages. Every page goes through them in order; a page that gets stuck at any of them does not show up in search.
1. Crawling: how does Googlebot find pages?
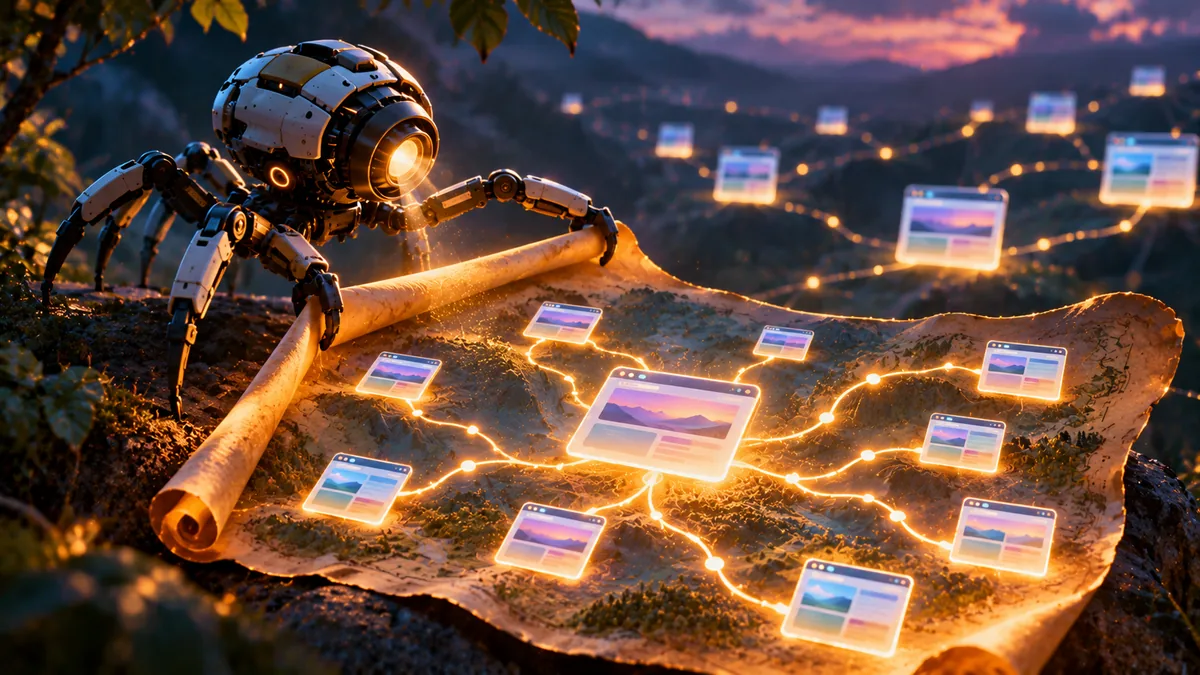
Google has a program called Googlebot. Think of it as a reader wandering the internet: it opens a page, reads it, notes the links on it and moves on to the next one. That is where the spider metaphor comes from, and why we call the internet a "web".
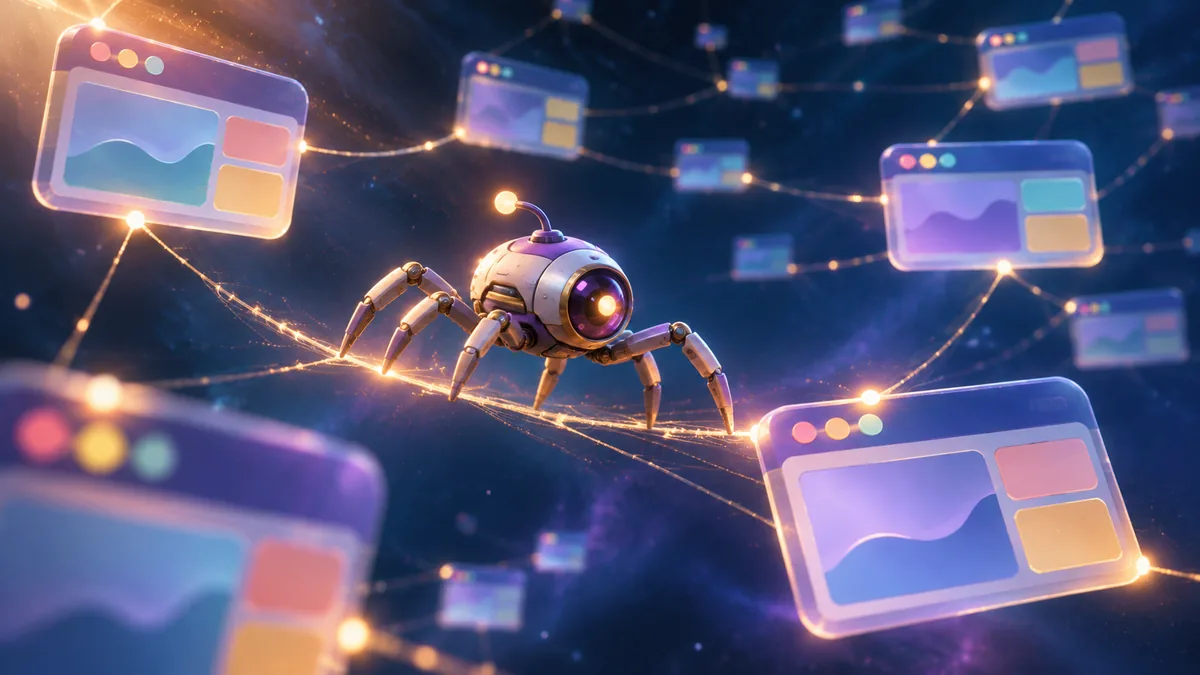
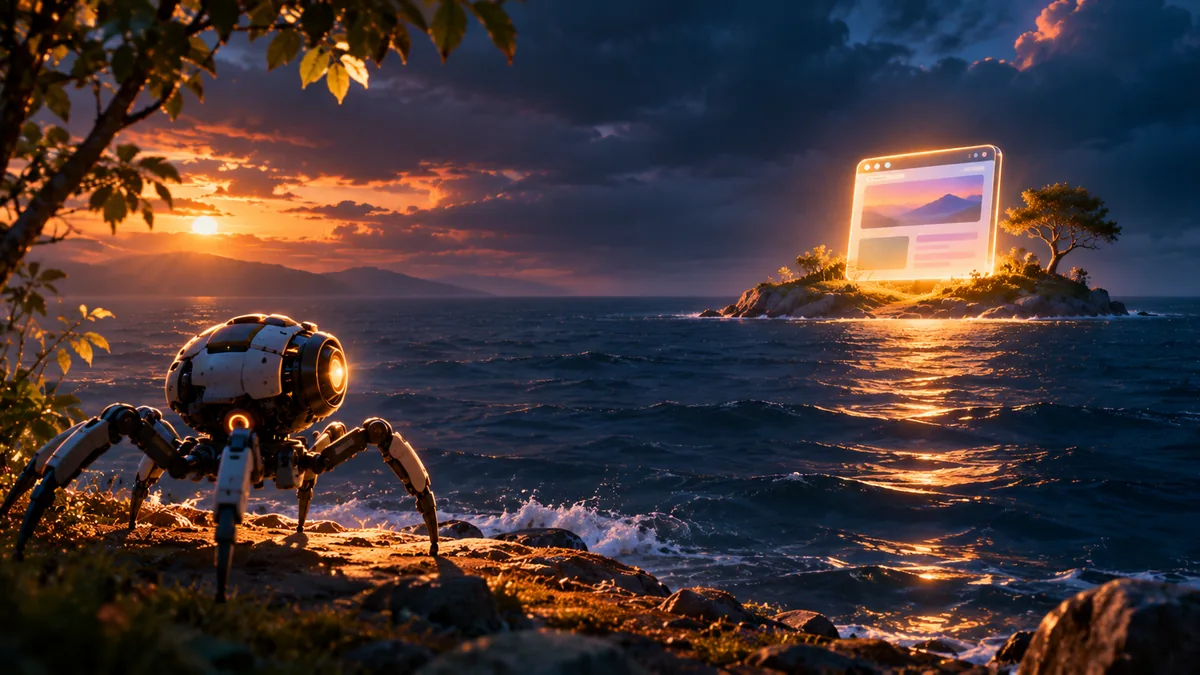
This has an important consequence: a page that no other page links to is like an island with no bridge. The robot has no way to get there. That is why site owners also give Google a map: a sitemap, a list that says "these are my pages".
The opposite is possible too. With a small file called robots.txt, a site owner can tell the robot "do not enter this section", and Google respects that sign. For more detail on crawling, see our guide to crawling and robots.txt.
2. Indexing: noindex and duplicate pages
The robot brings back the page it has read and Google analyses it: what is the page about, what is its title, which language is it in, does it contain images or video? Then the page takes its place in the index. But not every page that is read makes it into the index.
A page's code can contain a one-line marker: noindex. It means "you may read me, but do not put me in the index". Because of this one line, added while a site is being built and then forgotten, a page can stay live for years without appearing on Google even once. It is a common mistake.
Then there is the duplicate problem. The same page may live at three different addresses on a site: with "www", without "www", or with a small addition at the end. Google does not index them separately; it picks one as the main page (the canonical URL) and treats the others as duplicates. The site owner can mark the preferred one. If they do not, Google chooses, and sometimes it picks an address you did not want.
Time is part of it as well. According to Google's help pages, crawling a new or changed page can take anywhere from a few days to a few weeks. A site launched today not being on Google tomorrow morning is not a bug; it is how the system works.
3. Serving results: why does Google put one page on top?
This is the part that starts the moment you tap Search. Google looks in its index and finds the pages that could answer your question: sometimes thousands, sometimes millions. But only one can sit in first place.
This is where the two students' real invention from 1996 comes in. Their idea: every link from another page to a page is like a vote. But not all votes are equal; a vote from a highly trusted page counts for more than one from an unknown page. The idea is called PageRank, named after Larry Page's surname. It was the idea that set Google apart from other search engines in its early years.
Today things are far more complex. Google says it takes many factors into account when ranking: the meaning of your query, how well a page answers it, how fast the page is and whether it works properly on a phone. Even you: where you are and which language you use. Someone typing "coffee shop" in London sees different results from someone typing the same words in Manchester.
Can you pay to get to the top? Where do AI summaries come from?
The results marked "Sponsored" at the top of the page are ads, and they are placed through an auction. In the regular results below them, according to Google, you cannot buy a position; advertising does not affect regular rankings. So there are two separate races on the same page: one is won with a budget, the other through those three stages.
In recent years, for some searches and in some countries, an AI-written summary also appears at the top of the results. Under that summary there are source links too: the AI does not invent the answer from nothing, it draws on the same index and the same crawled pages. A page that is not in the index cannot appear in that summary either. We cover how these summaries affect traffic in our article on Google AI Overviews.
How big has Google's index grown?
According to Google's own blog in 2008, the first index in 1998 contained 26 million pages. By 2000 it had reached one billion pages. And in 2008 Google's systems had counted one trillion unique addresses on the web. The copy that started in a LEGO box now holds hundreds of billions of pages.
There is perhaps an even more surprising number: according to Google, about 15 percent of the searches made every day have never been searched before. Even though billions of people have been searching for more than twenty years, nearly one in six searches typed each day is a string of words Google has never seen. Google answers those from the same index too.
Is your site on Google? Three ways to check
Let us bring this into everyday life. Picture a bakery with a lovely website. If the site still has a forgotten noindex line, or if no page links to it, the bakery does not exist for Google: like a shop in the middle of the street whose door you cannot see.
- A site: search. Type site: into Google's search box followed by your domain with no space (for example site:examplebakery.com). Google lists the pages from that site it has in its index. If the list is empty or an important page is missing, that page may be stuck at one of the three stages. This is not an exact count, just a quick hint.
- Search Console. Google's free tool for site owners. After adding your site you can see which pages are in the index and why others were left out. You can also request crawling for a new page. But that request is like a queue ticket; it does not mean the page will be indexed right away.
- Our free SEO check tool. Enter your page address on our SEO check page. The tool reads the page much as Google's robot would and shows on one screen whether there is a noindex, whether the title and description are in place and whether the page is mobile friendly. No sign-up needed.
A common mistake: in systems such as WordPress, the option "discourage search engines from indexing this site" is switched on while the site is being built and nobody turns it off at launch. If none of your pages show up in a site: search, check this first.
Next episode: the internet comes from the ocean floor
Once Google has found the answer, how does it reach your phone? Most of us think the internet lives in the air, in the cloud. In fact most of it travels through cables on the ocean floor. In the next episode of Behind the Screen we follow those cables.
Read episode 2: What Happens If the Internet Goes Down? 1.5 Million Kilometres on the Ocean Floor
Sources and related pages
- Google Search Central: In-depth guide to how Google Search works (crawling, indexing, serving)
- Google: Organizing information, the Search index (hundreds of billions of pages, over 100,000,000 GB)
- Google: Ask Google to recrawl your URLs (days to weeks)
- Google: Duplicate pages and canonical URLs
- Google: Ads on Search
- Stanford: the origin of the name "Google"
- Google Blog (2008): We knew the web was big
- Search Engine Land: 15% of searches are new
- What is crawling? robots.txt, E-E-A-T and AI SEO
- TurkWebSite on YouTube: the Behind the Screen videos (in Turkish).
Does your site show up on Google?
Enter your page address and see noindex, title, description and mobile friendliness on one screen. If something is wrong, we can fix it together with our SEO packages.