What Is Crawling? robots.txt, E-E-A-T and AI SEO
What is crawling, and how do search engine and AI bots crawl websites? We cover robots.txt mistakes, how it differs from noindex, Google's E-E-A-T framework, broken link checks, and the role Wikipedia, Reddit and Quora play in brand reputation.
What Is Crawling? A Comprehensive SEO Guide to robots.txt, Google E-E-A-T and AI Bots
For a website to be visible in Google search results or AI-powered search systems, those systems first have to be able to reach the information on it. Yet many businesses invest in content production, keyword research and SEO work without examining closely enough whether their website can genuinely be crawled by search engines.
Understanding how search engines and the AI systems gathering information on the web actually work is one of the important parts of a successful digital visibility strategy.
The process of discovering and examining the pages on websites is called crawling. In that process, automated software follows links across the internet to reach pages, examines the content it can access and gathers various information.
A website being crawlable does not mean it will definitely rank highly in Google or be recommended by AI systems such as ChatGPT, though.
Alongside crawlability, technical SEO, content quality, trustworthiness, expertise and the brand's reputation across the internet all have to be considered.
This is where the robots.txt file, Google's E-E-A-T approach, off-site brand visibility and user-generated content all become important.
So what is crawling, how do search engine bots crawl websites, what mistakes are made in robots.txt files, and how can a business build a trustworthy brand identity on the internet?
In this guide we examine the technical structure of website crawling, the common SEO mistakes, Google's E-E-A-T concept, and the role platforms such as Wikipedia, Reddit and Quora play in digital brand visibility.
What Is Crawling? What Does Website Crawling Mean?
Crawling is the process search engines and other automated information-gathering systems carry out to discover web pages on the internet and examine their content.
That process is run by software known as crawlers or web crawlers.
They are also referred to as search engine bots or spider bots.
Googlebot, which Google uses to crawl web pages, is one of the best-known examples of this kind of software.
When a web crawler reaches a particular page, it can examine the page's HTML content and related resources, depending on the technical access conditions.
It can then discover the links on the page and try to reach other addresses.
That process helps map the structure of how web pages across the internet connect to each other.
How Do Web Crawlers Work?
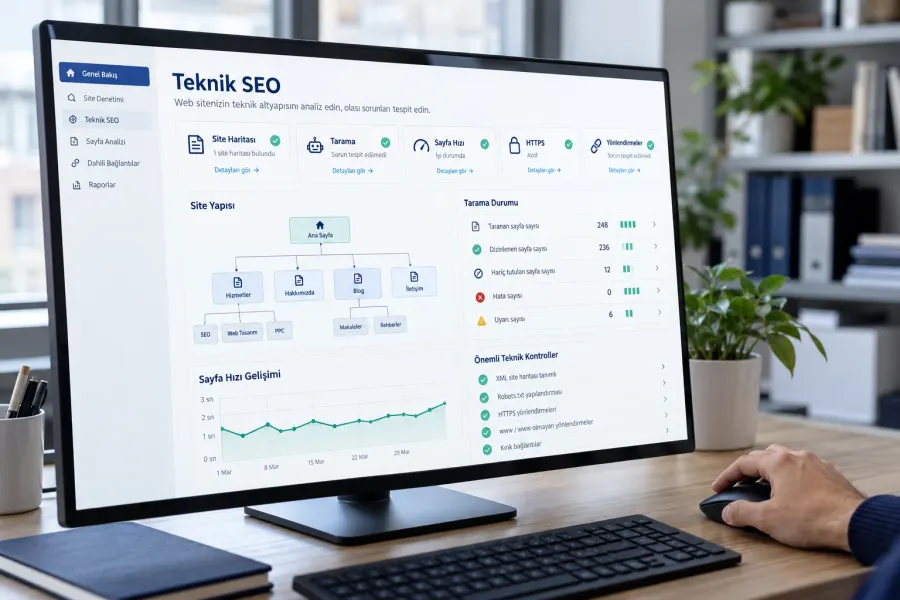
To understand how a web crawler works, let us imagine a simple website.
Say the site has a homepage, an about page, service pages, a blog and a contact page.
When the crawler reaches the homepage, it can examine the page's content. It can then detect the links on the homepage and move to the other pages.
If the homepage has a link to the services section, the bot can follow that link, for example.
The services page may contain pages for different services such as corporate website design, e-commerce site setup and SEO consultancy.
The bot can discover those links too and reach the rest of the content on the site.
In the same way, informational content can be discovered through the article links on the blog page.
This process gives bots the chance to examine how the pages on a website relate to each other and which subjects are covered.
It should not be assumed that every bot crawls the same pages in the same order, though. Crawl behaviour can vary with the system's characteristics and the website's technical state.
The Differences Between Crawling, Indexing and Ranking
Three concepts that come up often in SEO work are crawling, indexing and ranking.
Although they are related, they do not describe the same process.
Crawling: the process of a search engine discovering a web page and examining the content it can access.
Indexing: the process of the search engine including information about the page it has evaluated in its search index.
Ranking: the ordering of the results considered suitable for a particular search query after various evaluations.
A page having been crawled does not mean it has necessarily been indexed.
In the same way, there is no guarantee that an indexed page will rank highly for a particular keyword.
A newly published blog post may have been visited by Googlebot, for example. But after evaluating the page's content and other conditions, Google may choose not to index it.
Even if the page is indexed, it may not be visible enough for the relevant queries.
Website owners therefore need to evaluate crawling, indexing and ranking separately.
How Do AI Bots Crawl Websites?
AI-powered search systems can also use different methods to reach information on the internet.
Some systems can access current pages using web search tools and crawling infrastructure.
Others can build answers for certain tasks from model knowledge acquired earlier.
It is therefore wrong to think every AI application re-crawls the internet for every user question.
The web crawlers AI systems use and the data-gathering processes used in training models can also be different from each other.
A web page being crawled by a particular AI bot does not mean all the information on the page has been permanently taught to a model.
That said, websites being technically accessible does matter for systems searching the internet for information to be able to reach the relevant pages.
Which Pages Should AI Systems Be Able to Reach?
Not all of a business's web pages are equally important.
Temporary campaign pages, old announcements or technical pages used only for specific operations may not explain the business's core activities, for example.
Some pages, by contrast, play an important role in understanding the business's digital identity.
These can include the homepage, the about page, the core service pages, product descriptions, contact details and the content describing areas of expertise.
If a web design company's homepage contains only a short introductory sentence while the detailed service descriptions sit on other pages, it matters that those pages are discoverable.
In the same way, the pages where a manufacturer explains its product materials, production methods and use cases must be accessible.
The crawlability of those pages can support automated systems in discovering more information about the business's areas of activity.
Why Does It Matter That Your Website Is Crawlable?
A business may have prepared excellent content. But if technical problems prevent search engines from reaching that content, the impact of all that work is limited.
The about page may describe the business's genuine experience built over many years, for example.
But if that page's link is prepared incorrectly or bot access is blocked, the relevant systems cannot crawl it.
In the same way, one of the important services a business offers may be completely disconnected from the rest of the website.
A page like that becomes much harder to discover.
A page not being reachable by clicking from the homepage does not mean search engines can never discover it, though. Bots can also reach URLs through XML sitemaps, links from other websites and various other discovery methods.
That said, connecting important pages within a logical site architecture both makes navigation easier for visitors and supports crawling.
How Do You Check Your Website's Crawlability?
You do not have to use complex software at the first stage of checking website crawlability.
On websites with a small number of pages in particular, the basic checks can be done manually.
First, open the website's homepage and examine whether the important sections can be reached through links.
The links in the main menu can be checked one by one.
Whether the about, services, products and contact pages point to the correct addresses should be assessed.
The links within the pages should then be checked.
If a service page has a link to another service, make sure that link works, for example.
A link being clickable manually does not guarantee that every search engine bot can process it the same way, though.
Crawlability should be examined separately for complex navigation structures built with JavaScript in particular.
How Do Broken Links Affect SEO?
A broken link is one that cannot take the user or the crawler to the expected content.
If a web page links to another page that has been removed, the visitor can hit a 404 error page, for example.
That harms the user experience.
Broken links can also make it harder for bots to reach the relevant pages within the site and cause crawl resources to be used inefficiently.
It should not be assumed that every 404 error is necessarily an SEO problem, though. A page that has genuinely been removed with no suitable replacement content returning a 404 response can be perfectly normal.
What matters is identifying the links sending users or search engines to the wrong addresses.
Broken links can be checked manually or examined with website crawling tools built for the purpose.
How Do You Fix Broken Links?
When a broken link is detected, first establish the cause.
The link address may have been typed incorrectly.
The target page may have moved to a different URL.
The page may have been removed entirely.
A mistyped link can be replaced with the correct URL.
If the content has moved permanently to a new address, a 301 redirect can be used where appropriate.
If the page has been removed and there is no other relevant content to replace it, the link can be removed or redirected to a genuinely suitable alternative page.
Redirecting every 404 page to the homepage is not the right solution. Redirects need to match the user's expectation.
Checking Website Crawling with Google Search Console
Google Search Console is a free tool that helps website owners examine their site's status in Google's search systems.
It provides important information you can use in SEO work.
Your website's indexing status, information about specific URLs and various technical problems can all be evaluated through Search Console.
On large websites in particular, manual checks alone may not be enough.
On an e-commerce site with hundreds or thousands of pages, examining every link one by one takes a great deal of time.
In cases like that, using Search Console together with suitable website crawling tools is far more effective.
Which Areas Should You Check in Google Search Console?
Start with the page indexing reports.
Through those reports you can assess which pages Google has indexed and where it has detected different statuses.
The URL Inspection tool can then be used for important URLs.
That tool can provide information about whether a particular page is known to Google and its crawl and indexing status.
The information Search Console provides relates to Google, however.
A page appearing as indexed in Search Console therefore does not prove it is accessible or usable by every AI system.
How Does an XML Sitemap Help the Crawling Process?
An XML sitemap is a file that helps declare the important URLs on a website to search engines.
It can be especially useful on websites with a large number of pages.
Product and category pages on an e-commerce site, or articles on a blog, can be presented in a more organised way through a sitemap.
A URL being added to an XML sitemap does not mean that page will definitely be crawled or added to the Google index, though.
A sitemap is one of the tools that supports page discovery.
It is therefore just as important to make sure your important URLs work correctly, that the relevant pages can be reached from within the site, and that there are no technical access blocks.
What Is robots.txt and What Does It Do?
robots.txt is a text file used to declare rules about the crawling of certain URL paths on a website by automated crawler bots.
That file is generally located at the root of the website.
The robots.txt file of a website with the domain www.examplesite.com would normally be viewable at www.examplesite.com/robots.txt, for example.
robots.txt can tell supporting bots which URL paths you do not want crawled, or which areas access is appropriate for.
One of the most important distinctions about this file is this:
robots.txt is not a security tool or an indexing tool that directly removes a page from the Google index.
Its core function is to direct the crawl behaviour of bots that follow the rules.
Blocking a URL from being crawled and preventing it from being shown in search results are not the same thing.
What Happens If There Is No robots.txt File?
Not every website has to have a robots.txt file.
The absence of that file is not in itself a technical SEO error.
On a website without robots.txt, crawler bots simply do not encounter the extra crawl restrictions that file would create.
That does not mean every URL will definitely be crawled, though.
Server responses, access permissions, link structure and other technical conditions can all affect crawling.
Some content management systems can generate a robots.txt file automatically or serve it virtually at that address.
A website can therefore have a robots.txt file even if the site owner never prepared one directly.
What matters is understanding what the existing rules mean.
Common SEO Mistakes Made in robots.txt Files
Incorrect settings in a robots.txt file can block important pages from being crawled.
These problems show up especially on older websites, on projects that have undergone many technical changes, and on corporate websites managed by different teams.
Crawling of certain directories may have been blocked during the website's development phase, for example.
If those restrictions were never lifted after the site went live, access problems for important pages can arise.
In the same way, rules belonging to an application used in the past may not suit the new website structure.
It therefore matters not only that a robots.txt file exists but that its content is prepared correctly.
Accidentally Blocking the Entire Website from Being Crawled
One of the most serious mistakes is creating a crawl restriction for the whole website.
Using a User-agent: * line followed by Disallow: / in robots.txt tells all rule-following bots not to crawl any URL path starting from the website's root.
If a rule like that is accidentally carried over to the live website, it can cause serious crawl problems.
Care is needed in particular when transferring rules used in development and test environments to the live environment.
Checking the robots.txt file again after a website goes live is a useful practice.
Accidentally Blocking the About Page
The about page is one of the important sections describing a business's identity and areas of expertise.
Blocking that page with robots.txt can prevent rule-following bots from crawling the current information on it.
If the services the business offers, its field of activity or its expertise are described in detail only on the about page, that page's accessibility matters a great deal.
In the same way, accidentally blocking the contact page or the core service pages causes problems.
When checking robots.txt, therefore, examine not only the homepage but the URL paths containing the business's important information too.
Not Checking Old robots.txt Rules
Websites change over time.
New pages can be added, old content removed, the URL structure renewed and different software platforms adopted.
The robots.txt file may not be updated to match those changes, however.
A directory that previously held only technical files may later have started being used for content users need to reach, for example.
If the old robots.txt rules are left as they are, the new content can be blocked from crawling.
The robots.txt file should therefore be reviewed especially after major website updates.
What Is the Difference Between robots.txt and noindex?
robots.txt and noindex are two different mechanisms that often get confused.
robots.txt is used to direct bots' crawl behaviour for certain URL paths.
noindex is a directive telling supporting search engines that a particular page should not be added to the index.
If you do not want a page to appear in the Google search index, a properly used noindex directive can be considered, for example.
There is an important technical detail here, though.
For the search engine to see the noindex directive on the page, it generally has to be able to crawl that page.
If the page is blocked by robots.txt, the bot may not be able to read the noindex directive inside it.
A URL blocked by robots.txt can also appear in search results without a content description under some conditions, when it is discovered through other links.
robots.txt should therefore never be used on its own as a definitive indexing block.
Does robots.txt Protect Private Information?
No. robots.txt is not a security system.
A URL being blocked in robots.txt does not mean internet users cannot open it.
Not all automated software is obliged to follow robots.txt rules either.
Sensitive content such as personal information, private documents, admin panels or customer data must therefore never be protected with robots.txt alone.
Content that needs to stay private requires proper authentication, access control and server security methods.
The purpose of robots.txt is not to provide privacy but to direct crawl behaviour.
How Should robots.txt Be Approached for AI Bots?
The web crawlers associated with AI systems do not all share the same rules or the same purposes.
Some bots are used in search and information-retrieval processes, while others serve different data-gathering purposes.
When making access decisions about AI bots, you should therefore examine what the bot is for and which rules it supports.
A business may want its content to be findable in live search systems while holding different preferences about certain data-gathering activities, for example.
Those two things are not the same.
A blanket block in robots.txt can create access restrictions the site owner never intended.
Businesses aiming for AI visibility should therefore not make robots.txt changes without a plan.
Bots' crawl access, visibility in the search index and the use of data in AI model training all have to be considered separately.
What Is Google E-E-A-T?
Google E-E-A-T is an important conceptual framework used to evaluate the quality and trustworthiness of content.
E-E-A-T is made up of the initials of four words:
- Experience
- Expertise
- Authoritativeness
- Trustworthiness
This approach helps address questions such as who prepared the content, which experience it rests on, the level of expertise on the subject and how trustworthy the information it presents is.
E-E-A-T is connected in particular to Google's evaluation approach for search quality.
But E-E-A-T should not be thought of as an independent ranking factor that gives a website a single numerical score or is used directly.
These concepts, used in Google's quality evaluation approach, offer a useful framework for understanding content quality.
In the same way, it is wrong to assume every AI system uses Google's E-E-A-T approach exactly as it stands.
That said, qualities such as experience, expertise and trustworthiness are important parts of preparing content that is valuable to users.
Why Does Experience Matter Within E-E-A-T?
Experience is about having genuine practical or usage knowledge of the subject the content discusses.
Someone can describe the assembly process, usage characteristics and problems they encountered with a desk they bought, for example.
Those explanations can rest on the experience that comes from having genuinely used the product.
In the same way, a web design specialist can explain the technical problems they encountered on their projects and the solutions they applied.
Experience of that kind gives content information that goes beyond general definitions.
Having experience is not the same as having technical expertise in every area, though.
Having used a product for a long time can provide usage experience, while making definitive assessments about the product's technical safety or engineering characteristics requires different expertise.
Experience-based explanations and technical claims requiring expertise should therefore be kept apart.
How Is Expertise Demonstrated Within E-E-A-T?
Expertise expresses knowledge and competence on a particular subject.
A person's educational background, professional experience, technical knowledge and the work they have carried out can all support their expertise.
The same kind of proof of expertise is not sought on every subject, though.
In content prepared on an important health subject, the relevant professional qualifications and accurate information matter a great deal, for example.
In an assessment of a wooden piece of furniture in everyday use, by contrast, genuine user experience is what helps.
What matters for website owners is that it is clear which body of knowledge the content rests on.
A business can prepare explanatory guides about the services it offers.
It can share real examples of its work.
It can explain the methods it uses on its projects, with technical detail where appropriate.
But using only phrases such as "expert team" or "the best in the industry" does not prove expertise on its own.
How Is Authority Built Within E-E-A-T?
Authority, or authoritativeness, is about the extent to which a person or brand is recognised by others on a particular subject and considered a trustworthy source of information.
A business can describe its areas of expertise on its own website.
But a business making positive statements about itself does not reflect its whole reputation in the wider world.
Information published about the brand by other people and organisations therefore matters too.
A manufacturer being covered in an industry publication, appearing at an event related to its field, or being reviewed by genuine customers can all support the brand's recognition.
It should not be assumed that every brand mention carries the same value, though.
Content that is irrelevant, of low credibility or prepared purely to create links should not be treated the same way as genuine signals that strengthen brand authority.
Digital authority should be built as far as possible on real activity, trustworthy information and recognition that forms naturally.
Why Is Trustworthiness Decisive Within E-E-A-T?
Trustworthiness is about content or a website presenting accurate, honest and reassuring information.
A business stating its product features accurately, explaining its service scope clearly and avoiding misleading phrasing all matter for trustworthiness.
On an e-commerce site, the product's material, dimensions and usage characteristics must reflect reality, for example.
A service provider must never present features it does not offer as if they were included in the package.
Contact details must be current, and customers must be able to reach the basic explanations they need easily.
Trustworthiness is not only about how text is written.
It also relates to the business's real working methods, customer relationships, transparency and the accuracy of the information it provides.
Building a trustworthy digital identity is therefore a far broader process than making SEO changes.
The Relationship Between E-E-A-T and AI SEO
AI-powered search systems can draw on different information sources while building answers to users' questions.
The sources those systems use and their evaluation methods vary from platform to platform.
But building a brand that offers accurate, comprehensive and consistent information on the internet is useful for both traditional SEO and AI-focused visibility.
If a business's field of activity is stated only briefly on its own website, there is limited information about it in the digital environment, for example.
If there are real projects, current service descriptions, industry work and independent assessments about the business, by contrast, a far richer information environment exists.
That can support the brand being represented more clearly across different internet sources.
It should not be assumed that improvements related to E-E-A-T guarantee a particular ranking or recommendation outcome in AI systems, however.
Off-Site SEO and Digital Brand Reputation
A business's visibility on the internet is not limited to its own website.
Content published on other websites, genuine user reviews, industry news and community discussions are all parts of the brand's digital presence.
Off-site SEO is the broad area of work that considers these related elements outside the website.
In traditional SEO, links from other websites are among the important topics.
But reducing brand visibility to link counts alone is wrong.
The contexts in which a business's name appears on the internet, the subjects it is associated with and how it is assessed all matter for brand reputation.
A furniture maker being featured in an industry publication about wood materials can create visibility connected to its area of expertise, for example.
The same promotional text published on hundreds of irrelevant websites, by contrast, offers no comparable value.
What Is a Brand Mention? How Does It Affect SEO and AI Visibility?
A brand mention is a business or product being named in other digital content.
Those mentions are sometimes accompanied by a link and sometimes carry only the brand name.
A technology blog mentioning a particular software company's product creates a brand mention, for example.
A real customer sharing their experience with a product they bought on a forum can be assessed in the same way.
Brand mentions can extend a business's presence on the internet across a far wider area.
It cannot be said that every brand mention makes a direct, measurable contribution to Google rankings or AI answers, though.
What really matters is the business building trustworthy digital visibility connected to its field of activity.
What Can You Do to Increase Brand Visibility?
A business can focus on activities that help more people discover its real work.
A firm developing a new product can prepare a detailed introduction explaining the product's technical features and use cases, for example.
It can get in touch with industry publications.
It can attend suitable events.
It can share its real projects and experience.
It can contribute to community discussions related to its area of expertise.
The aim of these activities should not simply be creating links for search engines.
A business genuinely providing useful information to its target audience builds a far more sustainable brand visibility strategy.
Why Does Wikipedia Matter for Brand Authority?
Wikipedia is a large online encyclopedia project developed by users and volunteer editors.
It contains encyclopedic information about a great many people, organisations, concepts and events.
It therefore holds an important place in the internet's information ecosystem.
Wikipedia's core purpose is not to promote businesses, though.
For a Wikipedia article about a business to be created, the subject has to be notable in encyclopedic terms and to have been covered sufficiently in trustworthy, independent sources.
A company simply existing, or having comprehensive descriptions on its own website, may not be enough for a Wikipedia article.
Can Every Business Create a Wikipedia Page?
There are articles about companies on Wikipedia.
But it should not be assumed that every business has the right to create an article about itself.
A business being covered meaningfully in enough independent sources matters in the notability assessment.
Business owners or employees creating articles about their own brands can also lead to conflict-of-interest problems.
Wikipedia's rules on neutrality and conflict of interest have to be taken into account.
Wikipedia should therefore not be treated as an advertising platform for newly founded businesses to promote themselves directly.
A business creating untrue information in order to appear on Wikipedia, or arranging promotion under the appearance of independence, is not an appropriate approach.
The better method is for the business to carry out real work in its own field and for that work to be covered naturally in suitable independent publications.
What Is Reddit? How Is It Used for Brand Visibility?
Reddit is a platform where users can form communities around particular subjects and take part in discussions.
In communities devoted to different interests, users can ask questions, share their experience and make recommendations.
That content can help people research genuine user experience of products or services.
Some discussions on Reddit can also be discovered through search engines.
Reddit is therefore one of the platforms worth considering for understanding the user questions in the industries brands operate in.
How Should a Business Promote Itself on Reddit?
Reddit communities are generally shaped around specific rules and user expectations.
Sending the same advertising text to every community, or posting irrelevant content, is therefore not a sound strategy.
A business can start by examining the communities related to its field.
It can assess which problems users are having, which subjects they are curious about and which information they find useful.
A business offering web design services can contribute by providing information in response to questions about website performance or mobile compatibility, for example.
That contribution has to be genuine and explanatory, though.
A person connected to the business presenting themselves as an independent customer, or creating fake reviews, is not a trustworthy method.
Where the relevant community rules permit it, stating the connection to the business openly is the better approach.
Do You Need to Start a Brand Community on Reddit?
Some businesses choose to create a Reddit community for their brand.
That method is not necessary for every business, though.
For a community to be useful, it has to attract genuine users and sustain real discussion.
The users of a software product with a large active user base can come together in a community to share their problems and suggestions, for example.
For a business with no active user base yet, by contrast, simply opening a community in the brand's name provides little benefit.
The decision to create a Reddit community should therefore follow the brand's real customer base and communication needs.
What Is Quora? How Does It Contribute to SEO and Brand Awareness?
Quora is a knowledge-sharing platform where users can ask questions on different subjects and answer those questions.
The platform hosts discussions on technology, business management, digital marketing, education and a great many other subjects.
One of the aspects of Quora worth considering for brand visibility is that users create questions that reflect their information needs directly.
A user might ask what they should watch out for when commissioning a professional website, for example.
Another user might want to compare e-commerce systems for small businesses.
These questions can help businesses understand their target audience's real information needs.
How Do You Prepare Useful Answers on Quora?
For effective knowledge sharing on Quora, the question first has to be answered directly.
If a user asks "which website platform is more suitable for small businesses?", the answer must not consist only of promotion for one particular brand.
The user's technical needs, product count, budget and site management expectations can all be explained.
The advantages and limitations of different systems can be assessed honestly.
If the business is explaining something related to itself, it must not hide that connection.
Creating fake questions using multiple accounts, praising your own brand as if you were an independent user, or publishing untrue recommendations is not a trustworthy brand strategy.
The right approach is to provide clear, genuinely useful answers to questions in your area of expertise.
Why Does User-Generated Content Matter?
User-generated content, often shortened to UGC, covers user comments, community posts, forum discussions and various reviews.
The descriptions a brand publishes on its own website and the experience of real customers are not the same kind of information.
A business promoting its own product will naturally emphasise its positive features.
In genuine user reviews, by contrast, the product's advantages, limitations and usage experience are all addressed together.
That information can be valuable for potential customers.
It should not be assumed that all user-generated content is accurate or impartial, though.
Forums can also contain incorrect information, misleading reviews and posts with an advertising purpose.
The quality, context and authenticity of user comments therefore matter.
How Do Fake Reviews and Paid Promotion Affect SEO?
Some businesses consider using paid reviews, ready-made promotional articles or bulk link services to gain visibility faster.
Work of that kind should be assessed carefully, though.
Paying a publisher for content production and publishing advertising under the appearance of an independent user review are not the same thing.
Paid collaborations must be disclosed appropriately and the relevant platforms' rules followed.
Creating fake customer reviews, starting positive discussions about a brand with fake user accounts, or buying links to mislead search engines is not a sustainable approach.
Practices like that can breach platform rules and damage brand credibility.
You also cannot conclude that a website is trustworthy simply by looking at an organic traffic estimate.
When assessing a potential publication or collaboration, the site's subject, content quality, real audience, advertising policies and reputation should all be examined together.
Developing work that can attract genuine users and trustworthy publications is a far healthier strategy than chasing short-term visibility.
Which Platforms Can You Use to Strengthen Brand Reputation?
A business's digital reputation should not depend on a single platform.
Depending on the field, industry publications, professional communities, genuine customer reviews and suitable social media platforms can all be considered.
For a business offering corporate services, being active in professional networks is useful, for example.
For a business selling consumer products, product usage experience and customer feedback matter.
A business developing technical products can share explanatory information in communities related to its area of expertise.
Trying to be present on every platform is not compulsory, though.
What matters is focusing on the places your target customers genuinely use and where the business can offer value.
That approach lets brand work be carried out in a far more planned way.
How Do You Correct Contradictory Information About Your Brand for SEO?
A business can have a great many pieces of content published about it at different times across the internet.
Services can change over time, the business can start operating in new areas, or it can withdraw some products from sale.
When old content is not updated, contradictory information about the brand can build up.
The homepage may state that the business only offers web design services while an old promotional article says it offers different services, for example.
In the same way, old contact details or brand descriptions used in the past can remain on the internet.
In that case, start by updating the web pages the business controls.
The profile and promotional areas the business can manage directly can then be examined.
If there is significant incorrect information in independent publications, a correction request can be sent to the publisher.
A business cannot change all the information about it on other websites directly, though.
Having accurate, consistent information clearly available on the business's own digital channels therefore matters a great deal.
A Worked Example: Checking a Web Design Company's SEO and Brand Visibility
Imagine a web design company wants to be represented more clearly in Google and AI-powered search systems.
Say the business offers corporate website design, e-commerce development and SEO services.
The first step for this business is checking the technical state of its existing website.
Stage One: Identifying the Important Pages
First, the business's homepage, about page, service pages and contact section are identified.
Whether those pages contain accurate, current information is examined.
Whether the service descriptions are detailed enough is assessed.
Rather than describing the e-commerce site design service in a single sentence, the scope of the service and which businesses it suits can be explained, for example.
Stage Two: Checking for Crawl Problems
The links in the main menu are tested.
Whether the important service pages can be reached from within the site is checked.
Broken links are identified.
Whether important pages have been blocked accidentally in robots.txt is examined.
The status of the relevant URLs is evaluated through Google Search Console.
Stage Three: Reviewing from an E-E-A-T Perspective
The business's real areas of expertise are identified.
That information is explained clearly on the about page.
Real projects and suitable references, where they exist, are presented on the relevant pages.
The accuracy of the information used in technical articles is checked.
Explanations based on real working experience can be added to suitable content.
Stage Four: Assessing Off-Site Visibility
The business name is researched in search engines.
The existing brand mentions are examined.
Old or incorrect information is identified.
The communities and industry publications related to the business's field are assessed.
The places where useful answers can be given to genuine user questions are identified.
The aim of this work is not simply gaining more links but developing a trustworthy digital identity connected to the business's field of activity.
A Website Crawlability and Brand Trust Checklist
Businesses that want to evaluate SEO and AI visibility work together can use the checklist below.
| Check area | What to examine |
|---|---|
| Homepage | Links to the core services and important information |
| About page | Current brand, activity and expertise information |
| Service pages | Content being detailed, accurate and accessible |
| Internal links | Checking broken or misdirected links |
| robots.txt | Important URL paths not being blocked accidentally |
| Indexing | Examining important pages through Google Search Console |
| Content quality | Accurate information, real experience and clear explanation |
| Brand information | Consistent descriptions and contact details across the site |
| Off-site visibility | Genuine, topically relevant brand mentions |
| User communities | Transparent, useful participation that follows platform rules |
| Trustworthiness | Avoiding fake reviews, misleading claims and artificial promotion |
These checks can be repeated at regular intervals depending on the website's current state.
Running crawlability checks again after major technical updates, domain changes or site migrations in particular is useful.
How Long Do Crawling and E-E-A-T Work Take to Have an Effect?
Fixing a technical problem related to website crawlability can make it easier for search engine bots to reach the relevant pages.
When those pages will be recrawled or indexed after the fix cannot be determined with certainty, though.
In the same way, there is no single timeframe for brand trust and expertise work that applies to every website.
A business explaining its real experience better in the digital environment can improve content quality.
Appearing in independent publications or earning genuine user reviews can support brand recognition.
But there is no guarantee that this work will lift search rankings by a particular date or produce recommendations in AI systems.
Crawling and E-E-A-T work should therefore be seen as ongoing processes of improvement and assessment rather than one-off tasks.
Conclusion: Building a Strong Digital Foundation for Search Engines and AI Systems
A website being visible in Google or AI-powered search systems is about more than preparing content.
Those systems being able to reach your web pages, important information being presented correctly, and the business's identity on the internet being understandable all matter too.
Crawling is one of the core processes allowing web pages to be discovered and examined by automated systems.
The robots.txt file can direct bots' crawl behaviour in that process. But incorrectly configured rules can block important pages from being crawled.
Google's E-E-A-T approach, meanwhile, helps you understand the importance of experience, expertise, authority and trustworthiness in evaluating content quality.
Alongside that, how the business is represented on other websites, which experiences real users share and what information exists about the brand are all important parts of digital reputation.
Platforms such as Wikipedia, Reddit and Quora can play a role in some businesses' information and visibility ecosystem. But those platforms should not be treated as places to promote yourself purely for SEO purposes.
Transparent participation based on real experience that provides value to users is a far healthier approach.
The priority for website owners is ensuring important pages are accessible, removing crawl blocks, preparing accurate content and explaining the business's real areas of expertise clearly.
A strong SEO strategy should aim not only at search engines being able to find the website, but at the content they find being accurate, understandable, useful and trustworthy.
That approach builds a far more solid foundation for digital visibility in both traditional search engines and the developing AI-powered information systems.